

Description
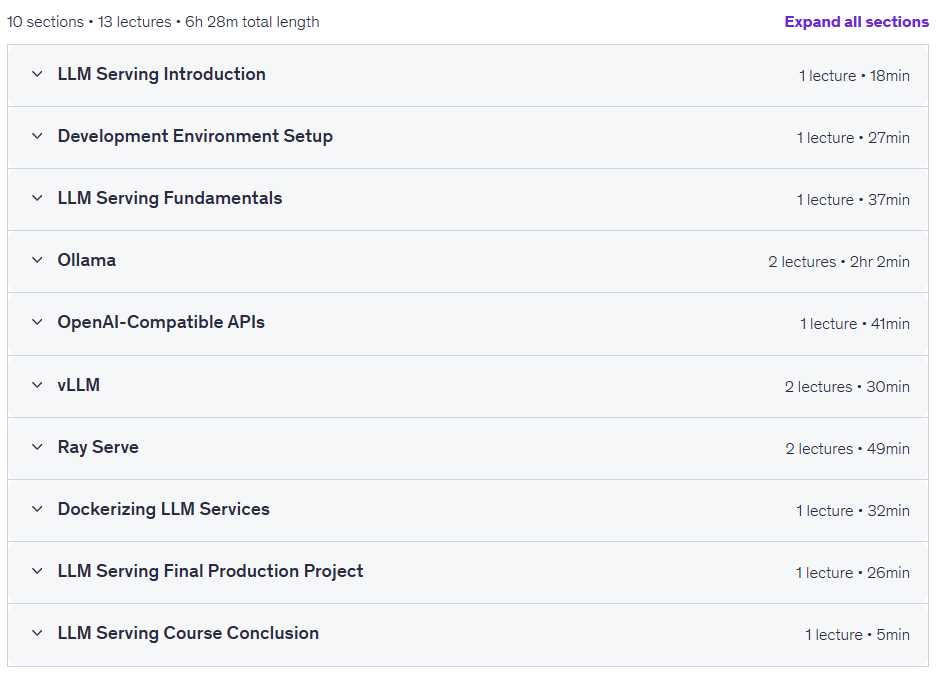
LLM Serving, Deployment & Scaling – Ollama, vLLM & Ray Serve. This course is a comprehensive and advanced program to learn the principles of serving, deploying and scaling large language models using tools such as Ollama, vLLM and Ray Serve. This specialized course from the Uplatz series focuses on the technologies, concepts and practical architectural patterns that are used to run, serve, deploy and scale large language models (LLM). Large language models are most effective when they are reliably and optimally served to applications, users and business systems. In this course, learners will be introduced to the fundamentals of inference and serving, including tokenization, token generation, latency, throughput, batching, KV cache, quantization and streaming responses. Next, Ollama is introduced as a simple and accessible platform for running models locally, and participants learn how to install, manage models, use the command line environment, call the API, and integrate local models with Python. It also teaches standards for OpenAI-compliant APIs so that applications can communicate with different infrastructures using standard request and response formats. The next part of the course focuses on high-performance serving with vLLM, including concepts such as PagedAttention, Continuous Batching, and GPU memory optimization. Then, Ray Serve is introduced for distributed deployment, orchestration, request routing, autoscaling, and fault management. Finally, the various system components are packaged using FastAPI, Docker, and Docker Compose, and the course ends with a comprehensive production project.
What you will learn
- Understanding the concept of servicing large language models and its difference from the model training process
- How inference works for large language models and converting prompts to tokens
- Latency and Throughput Management to Improve System Performance
- Improving GPU performance using batching and continuous batching
- Optimize memory usage and production speed using KV Cache and Quantisation technique
- Run and manage language models locally using the Ollama tool and call it via Python
- Using OpenAI-compatible APIs and the OpenAI Python library with various model infrastructures
- Increasing inference efficiency using vLLM and memory management with PagedAttention
- Distributed deployment and orchestration of AI applications using Ray Serve
- Request routing management, autoscaling, and fault tolerance
- Building a programming API layer using the FastAPI web framework
- Packaging applications and managing services using Docker and Docker Compose
- Implementing a comprehensive production project combining all course topics
This course is suitable for people who:
- Software developers and AI engineers who want to deploy large language models in real-world environments
- Machine learning engineers looking to learn techniques for optimizing inference and scaling systems
- Python programmers interested in learning advanced tools like Ollama, vLLM, and Ray Serve
- People who want to learn how to build and deploy scalable AI systems from scratch to production level
Course Details LLM Serving Deployment & Scaling – Ollama vLLM & Ray Serve
- Publisher: Udemy
- Instructor: Uplatz Training
- Training level: Beginner to advanced
- Training duration: 6 hours and 28 minutes
- Number of lessons: 13
Course headings
Prerequisites for the LLM Serving Deployment & Scaling course – Ollama vLLM & Ray Serve
- Enthusiasm and determination to make your mark on the world!
Course images
Sample course video
Installation Guide
After Extract, view with your favorite player.
Subtitles: None
Quality: 1080p
Download link
Rapidgator link
File(s) password: www.downloadly.ir
File size
2.2 GB