

Description
Mastering Parallel Programming with CUDA Platform. This course is a comprehensive and in-depth guide to learning parallel programming using GPU computing and C++, helping learners understand the fundamental concepts and implement parallel algorithms optimized for high-performance GPUs. This course is an informal and in-depth guide to parallel programming using GPU computing techniques and C++. The course begins with a review of fundamental concepts such as the GPU programming model, execution structure, and memory hierarchy, and then moves on to the practical development and implementation of advanced parallel algorithms optimized for high-performance GPUs. Since efficiency is at the core of GPU-based computing, this course has a strong focus on optimization techniques, teaching learners how to fine-tune their code for maximum speed and efficiency, and using industry-standard tools such as nvprof, nvvp, memcheck, and GDB-based GPU debuggers for profiling and debugging. The main sections of this course include an introduction to GPU programming concepts and execution models, understanding execution behavior on parallel processors, a close examination of memory systems including global, shared, and persistent memory, using streams to manage concurrent execution, fine-tuning instruction-level behavior to increase efficiency, implementing real-world algorithms with GPU acceleration, and an overview of profiling and debugging tools. To consolidate the learning, programming exercises and quizzes are included to ensure that each concept is well-rooted in the audience’s mind. This course is the first in a series of masterclasses on GPU-based parallel computing, and the knowledge gained will provide a solid foundation for learning more advanced topics in future courses. Given the increasing role of GPUs in innovation in areas such as artificial intelligence and scientific computing, mastering these tools and methods provides a significant competitive advantage in the technology industry. This course is not affiliated with or endorsed by NVIDIA, and the name CUDA is a registered trademark of NVIDIA, used in this course for educational reference purposes only.
What you will learn
- Gain all the basic knowledge about programming with the CUDA platform
- Ability to design and implement optimized parallel algorithms
- Introduction to the basic workflow in designing parallel algorithms
- Learn advanced concepts in CUDA
- Understand the GPU programming model, execution structure, and memory hierarchy including global, shared, and persistent memory
- Using streams to manage concurrent execution and optimize performance at the instruction level
- Working with profiling and debugging tools such as nvprof, nvvp, memcheck, and GDB-based GPU debuggers
This course is suitable for people who:
- Anyone who wants to learn CUDA programming from beginner to intermediate level
- Those interested in parallel computing and GPU processing with C++ who intend to implement optimized algorithms
- Programmers and professionals looking to build a strong foundation to enter more advanced GPU computing topics in areas such as artificial intelligence and scientific computing
Course details: Mastering Parallel programming with CUDA platform
- Publisher: Udemy
- Instructor: Kasun Liyanage
- Training level: Beginner to advanced
- Training duration: 10 hours and 47 minutes
- Number of lessons: 83
Course headings
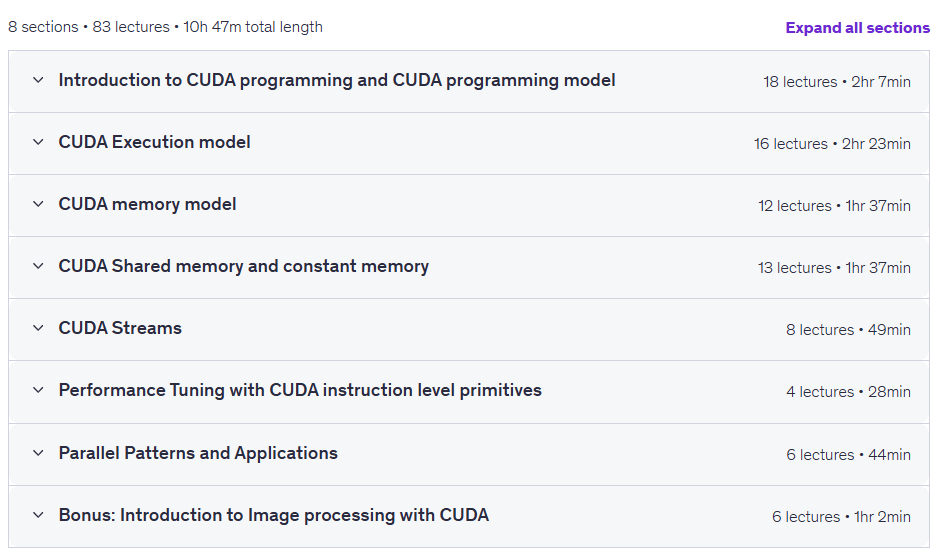
Prerequisites for the Mastering Parallel programming with CUDA platform course
- Basic C or C++ programming knowledge
- How to use Visual Studio IDE
- CUDA toolkit
- Nvidia GPU
- You should be familiar with basic setup of a C++ project, how to change project properties etc
Course images
Sample course video
Installation Guide
After Extract, view with your favorite player.
Subtitles: English
Quality: 1080p
Download link
Rapidgator link
File(s) password: www.downloadly.ir
File size
3.1 GB